Two major newsrooms accuse OpenAI and Microsoft of exploiting their journalism for AI training. The lawsuits spotlight growing risks for publishers as generative AI reshapes content economics.
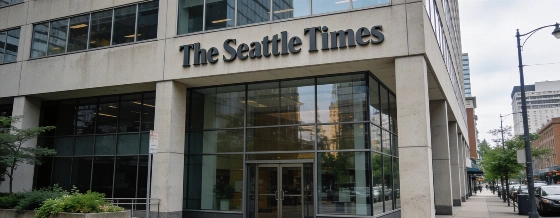
The Seattle Times and Newsday have filed lawsuits against OpenAI and Microsoft, accusing them of using newsroom reporting to train AI models. The publishers argue that this practice threatens the survival of organizations that produce original journalism.
According to the lawsuits, AI systems like ChatGPT and Copilot are "rapacious consumers" of human-authored reporting, returning derivative versions for commercial use. The filings warn that this cycle could damage the journalism industry, with AI models undermining the business models of the publishers whose work they use. Reuters reports that the lawsuits, filed on September 4, 2026, in federal court in New York, specifically accuse OpenAI and Microsoft of using articles from The Seattle Times and Newsday-including paywalled content-to train ChatGPT, Microsoft Copilot, and Bing's AI features.
The lawsuits demand not only monetary damages but also the destruction of any AI training datasets or models containing the publishers' copyrighted works.
This legal fight follows similar action by The New York Times in 2023, as more outlets challenge how AI companies use their content. The Seattle Times' case is notable because both Microsoft and OpenAI have previously funded the publisher's journalism projects and fellowships. Now, those same companies face accusations of undermining the newsroom's core product.
Microsoft responded by saying it was "surprised by the lawsuit" and is open to discussions, but did not address the main claims. The complaint alleges that "hundreds of thousands" of articles from The Seattle Times and Newsday were scraped and used in AI training datasets. The publishers are seeking damages and a court order to stop further use, as detailed in GeekWire's case summary.
For digital publishers, the risk is immediate. If AI models can generate content that mimics or repackages original reporting, it becomes harder to justify investing in journalism. As more AI tools appear in search, productivity, and content platforms, the line between original and derivative work blurs, making it difficult for publishers to protect their intellectual property and monetize their reporting. The lawsuits also claim that the companies scraped not only freely available articles but also those behind paywalls, raising concerns about unauthorized use of proprietary content, as confirmed in a Reuters legal report.
The broader legal context includes the U.S. government’s recent support for OpenAI in its dispute with The New York Times, with a September 2026 brief arguing that AI training on copyrighted materials may qualify as fair use under U.S. law. This intervention has intensified the debate over the boundaries of copyright in the era of large language models.
Legal action has become a necessary tactic for newsrooms seeking leverage in negotiations with AI developers. The lawsuits force a public debate over who controls the raw material of the information economy. As reported earlier, publishers are already testing new formats and strategies to keep audiences engaged and protect their editorial value as AI becomes more common.
This is now a direct standoff between established media and major tech companies. The fact that publishers are willing to sue former partners shows a shift from uneasy cooperation to open conflict. For content creators and media operators, the message is clear: publishers are no longer willing to accept unchecked AI training on newsroom output. The outcome will depend on whether publishers can secure meaningful changes-or if AI platforms will keep using journalism without compensation or consent.